
【我在L站搞科研】浅析 Kimi 会员计划模型计费制度:以 Allegro 套餐 Code 额度为例
订阅老版 Kimi 会员计划的 Allegro(699 元/月)套餐已有数月,日常高强度用下来一直对套餐内部的实际扣费规则比较好奇,恰逢近期 K3.1 系列上线,索性做了一轮定量实测,把 Code 额度下 6 个模型的计费方程、之前大家讨论好久的 K3 256K 阈值规则、折算官方 API 的回本价值以及各模型吞吐算了一遍,分享给佬友们一同探讨。需要说明的是,该套餐实际还包含月度总额度,但受限于无法通过 API 获取读数,且会与 Chat / Work 模式混合计费,因此本文仅讨论 Code 额度(5h / 7d 窗口),不讨论月度总额度及 Chat / Work 模式的计费制度。
叠甲声明:本文所有数据均基于单个老版 Allegro 账号在 2026 年 10 月 24–25 日的黑盒实测反推,仅代表测试当下的账户状态。正如测试期间 K3.1 系列权重在一天内就下调了 35%,官方后台随时可能动态调整计费系数与档位策略;文中的 API 折算金额与吞吐数据高度依赖具体使用场景及测试时段负载,仅供佬友们技术交流参考。实验脚本编写、数据拟合与图表绘制由 Gemini 4 Argon 与 Claude Opus 5.5 辅助完成,如有疏漏欢迎指正。
TL;DR
本文基于 2026 年 10 月 24 日早上与 10 月 25 日凌晨的两轮实测(文中时间均为 UTC+8),以老版 Kimi Allegro 套餐为样本,利用配额接口 GET /coding/v1/usages 中保留 4 位小数的 used_ratio 字段,通过控制变量实验反推出完整的计费方程与吞吐表现。核心结论如下:
7d/5h额度呈现 5 倍关系:套餐 7 天(7d)限额封顶为 5 个 5 小时(5h)限额。- 套餐内缓存读取极便宜、输出权重偏高:各模型缓存读取权重均约为未命中输入的 \frac{1}{200} (远低于国内站 API 的 \frac{1}{10} ),且无缓存写入溢价;K3 / K3.1 系列输出权重约为未命中输入的 8\times ,K2 系列为 10\times ,均高于国内站 API 的 4.2 \sim 5.2\times 。两个高速版分别为对应标准版的三项同步放大,而国内站 API 上高速版的缓存读取并不加价。
- K3.1 系列权重在两次测试间下调了 35%,消除了与
K3的倒挂但相对比例仍高于 API 价格比:国内站按量 API 上K3.1 Pro定价约为K3的 0.65 \sim 0.68\times ;10 月 24 日首轮实测时套餐内K3.1 Pro权重反而是K3的 1.31\times ,10 月 25 日凌晨复测时K3.1 Pro与K3.1 Pro Highspeed三项权重同步下调至首轮的 0.65\times (即K3的约 0.85\times ,仍高于两者在按量 API 上的 0.65 \sim 0.68\times 价格比),其余模型权重不变。 K3/K3-256k在实际总长 T_{\text{prompt}} + T_{\text{out}} > 256\text{K} 时整段输出按 2\times 计费:两者共享同一 KV Cache 池,计费权重完全相同;当输入加输出的实际总长超过 256\text{K} (而非按max_tokens声明上限计算)时,输入与缓存读取权重不变,整段输出按 2\times 计费。两者的唯一区别是仅当 T_{\text{prompt}} > 256\text{K} 时K3-256k会返回 400 报错。- Allegro 套餐折算国内站 API 的人民币等效价值:以典型长文编码场景(缓存命中率 h = 97.5\% 、未命中输入/输出比 r = 2.5 )为基准,按 10 月 25 日复测权重,
K3.1 Pro单次5h满额度等效国内站 API 220.4\text{ 元} ,单周7d满额度等效 1,102.0\text{ 元} (首轮权重下为 143.0 / 715.0\text{ 元} );同场景下K3(总长 \le 256\text{K} )单周7d满额度等效 1,423.1\text{ 元} 。 - 各模型流式吞吐(TTFT 与 TPS)实测排序: 51.2\text{K} 未缓存预填充阶段 K3.1 系列最快(比 K2 与 K3 快约一倍);长输出持续吞吐率从高到低依次为
K2.7 Code Highspeed>K3.1 Pro Highspeed>K2.8 Preview>K3.1 Pro>K3( \le 256\text{K} ) >K3-256k>K3( > 256\text{K} )。
1. 测试接口与权重反推方法
通过调用 Kimi 的配额接口 GET https://api.kimi.com/coding/v1/usages 可获取当前账户的额度状态, JSON 返回体中 .usages.limit_5h.used_ratio 与 .usages.limit_7d.used_ratio 提供了保留 4 位小数的已用比例。
单次请求的配额消耗由 usage 返回的三项 Token 决定:
- 未命中输入 T_{\text{in}} (
prompt_tokens - cached_tokens):未命中历史缓存的前缀部分(含末尾凑不够一整块缓存块 B 的零头)以及本轮新增输入,必须重新做 Prefill 计算,统一按未命中输入计费; - 缓存读取 T_{\text{cr}} (
cached_tokens):实测返回的 T_{\text{cr}} 恒为固定块大小 B = 256 Token 的整数倍,只有完整命中的块才计入缓存读取,末尾不足 256 Token 的零头归入 T_{\text{in}} ; - 总输出 T_{\text{out}} (
completion_tokens):包含思考链(reasoning_tokens)与最终回复正文,统一按输出计费。
记某模型在 5h 或 7d 窗口下每百万 Token( \text{M} )的三项扣费权重为 (w_{\text{in}}, w_{\text{cr}}, w_{\text{out}}) ,第 k 次请求后的累计百万 Token 数为 (S_{\text{in},k}, S_{\text{cr},k}, S_{\text{out},k}) 。由于接口返回的读数 y_k 是四舍五入到 4 位小数的,未四舍五入的真实累计消耗 y_k^* 与读数 y_k 的误差不超过半个最小步长 \delta = 0.5 \times 10^{-4} :
y_k^* = x_0 + w_{\text{in}} S_{\text{in},k} + w_{\text{cr}} S_{\text{cr},k} + w_{\text{out}} S_{\text{out},k}, \qquad \left| y_k^* - y_k \right| \le \delta = 0.5 \times 10^{-4}
其中 x_0 为初始真实已用比例,单步增量 \Delta y_j = y_j - y_{j-1} 的最大舍入误差为 2\delta = 0.00010 。通过将多轮控制变量请求的累计 Token 数与读数代入线性规划,即可直接解出三项权重的中心解及严格可行区间 [w_{q,\min}, w_{q,\max}] 。
2. K3.1 Pro 权重实测与 256-Token 缓存块对齐
2.1 六组控制变量实验与 B = 256 缓存块边界
对 K3.1 Pro 依次针对三个计费维度做控制变量调用(共 40 次调用、41 组 usage 读数,轨迹见图 1):先通过随机长文与短输入长输出分别测出 w_{\text{in}} 与 w_{\text{out}} ,并验证首次写入长前缀无额外溢价;针对权重极小的缓存读取 w_{\text{cr}} ,为避免末尾不足 256 Token 的未对齐零头混入 T_{\text{in}} 干扰测量,用单 Token 词 " apple" 将系统提示词对齐到 256 的整数倍( 51.2\text{K} / 100.1\text{K} ),使每轮新增未命中输入固定为 16 Token。将全部读数代入线性规划,求得中心解为 (0.143997, 0.000760, 1.155950)\,\text{M}^{-1} ,表 1 取整为 (0.14400, 0.000750, 1.15600)\,\text{M}^{-1} ,代回检验全部读数最大残差仅 0.48\times 10^{-4} < \delta 。
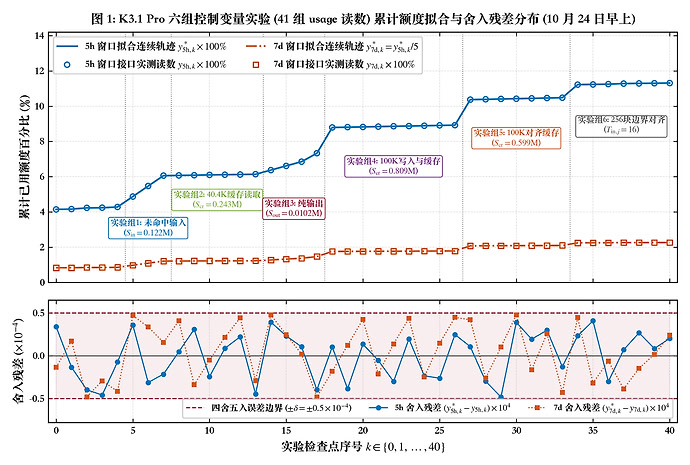
2.2 K3.1 Pro 首轮计费方程与国内站 API 定价对比
由拟合结果可得 K3.1 Pro 在 5h 与 7d 窗口的累计额度消耗方程:
\boxed{\Delta y_{5\text{h},k}^* = 0.14400\,S_{\text{in},k} + 0.000750\,S_{\text{cr},k} + 1.15600\,S_{\text{out},k}, \qquad \Delta y_{7\text{d},k}^* = \frac{1}{5}\,\Delta y_{5\text{h},k}^*}
其中接口读数 y_k = \operatorname{round}(x_0 + \Delta y_k^*, 4) 。基于上述公式,K3.1 Pro 的套餐权重与国内站开放平台(platform.moonshot.cn)官方定价对比见表 1。
表 1:K3.1 Pro 在老版 Allegro 套餐中的拟合权重与国内站 API 定价对比表(10 月 24 日首轮)
| 计费项 | 5h 窗口可行区间 ( \text{M}^{-1} ) | 5h 窗口权重 w_{q,5\text{h}} ( \text{M}^{-1} ) | 7d 窗口权重 w_{q,7\text{d}} ( \text{M}^{-1} ) | 5h / 7d 满额纯输入或纯输出 | 国内站 API 单价 P_q ( \text{元/M} ) | 套餐内部相对权重比 vs 国内站 API 相对价格比 |
|---|---|---|---|---|---|---|
| 未命中输入 ( \text{in} ) | [0.143850, 0.144171] | 0.14400 ( 14.40\% ) | 0.02880 ( 2.88\% ) | 6.94\text{M} / 34.72\text{M} | 13.00\text{ 元} | 1.000 vs 1.000 |
| 缓存读取 ( \text{cr} ) | [0.000703, 0.000792] | 0.000750 ( 0.075\% ) | 0.000150 ( 0.015\% ) | 1,333.3\text{M} / 6,666.7\text{M} | 1.30\text{ 元} | 约 0.00521 ( \frac{1}{192} ) vs 0.1000 ( \frac{1}{10} ) |
| 首次缓存写入溢价 | 未单独计费(归入 \text{in} ) | 0.00000 | 0.00000 | 按普通未命中输入计费 | 13.00\text{ 元}(5\text{分钟}) / 26.00\text{ 元}(1\text{小时}) | 无写入溢价 |
| 模型输出 ( \text{out} ) | [1.155080, 1.158198] | 1.15600 ( 115.60\% ) | 0.23120 ( 23.12\% ) | 0.865\text{M} / 4.325\text{M} | 68.00\text{ 元} | 8.028\times vs 5.231\times |
2.3 K3.1 Pro 复测(10 月 25 日凌晨)
10 月 25 日凌晨对 K3.1 Pro 重新做了 44 次调用(覆盖 41\text{K} \sim 128\text{K} 未命中输入、256-Token 对齐缓存命中与 2\text{K} \sim 4\text{K} 长输出),不同长度下拟合出的权重完全一致。复测与首轮的对比见表 1b:
表 1b:K3.1 Pro 两轮实测 5h 窗口权重对比( \text{M}^{-1} )
| 计费项 | 首轮(10 月 24 日早上) | 复测可行区间(10 月 25 日凌晨) | 复测取整值 | 复测 / 首轮 | 复测 / K3 |
|---|---|---|---|---|---|
| 未命中输入 w_{\text{in}} | 0.14400 | [0.09349, 0.09396] | 0.0936 | 0.650 | 0.851 |
| 缓存读取 w_{\text{cr}} | 0.000750 | [0.000466, 0.000480] | 0.000473 | 0.63 | 0.862 |
| 输出 w_{\text{out}} | 1.15600 | [0.7488, 0.7538] | 0.751 | 0.650 | 0.850 |
复测取整值 (0.0936, 0.000473, 0.751) 在 5h 与 7d 两个窗口下均吻合,内部比例为 1 : \frac{1}{198} : 8.02 ,与首轮基本相同,即三项按同一比例下调。K3.1 Pro Highspeed 同期复测(31 次)为 (0.1872, 0.000946, 1.502)\,\text{M}^{-1} ,依然为标准版的 2\times 。复测时 K3.1 Pro 的扣费权重降至 K3 的约 0.85\times ,消除了首轮的价格倒挂,但相对 K3 的比例仍高于两者在国内站 API 上的 0.65 \sim 0.68\times 价格比。
3. 全模型计费权重与 K3 的 256K 阈值测试
3.1 其余模型测试与 K3 256K 阈值控制变量实验
沿用相同的控制变量方法测出其余 5 个模型的权重(汇总见 3.2 节表 2),并重点验证了跨模型缓存互通性与 K3 / K3-256k 的 256K 阈值规则:
- 跨模型缓存互通性与同价关系:标准版与高速版之间、不同代模型之间切换时
cached_tokens均为 0 (缓存池相互独立);唯独K3与K3-256k共享同一缓存池(在K3-256k预热的 256\text{K} 前缀切到K3可直接 100% 命中),且两者的三项计费权重完全相同。 K3/K3-256k的 256K 阈值规则:在 253\text{K} \sim 333\text{K} 区间通过前缀缓存复用做了跨阈值对照测试(图 2(b))。实测超过阈值后未命中输入与缓存读取权重不变,仅输出权重 w_{\text{out}} 翻倍( 2\times );且一旦越过阈值,整段输出均按 2\times 计费。进一步将总长收窄至 255.3\text{K} \sim 256.2\text{K} ,确认触发条件为实际总长 T_{\text{prompt}} + T_{\text{out}} > 256\text{K} 。
按实际总长 > 256\text{K} 分段后,K3 与 K3-256k 的三项权重可行区间分别为 w_{\text{in}} \in [0.10998, 0.11001] 、 w_{\text{cr}} \in [0.000549, 0.000551] 、 w_{\text{out}} \in [0.88311, 0.88386]\,\text{M}^{-1} ,取整后为:
\left(w_{\text{in},5\text{h}}^{(\texttt{K3})},\; w_{\text{cr},5\text{h}}^{(\texttt{K3})},\; w_{\text{out},5\text{h}}^{(\texttt{K3})}\right) = \begin{cases}
(0.1100,\; 0.000549,\; 0.8836)\,\text{M}^{-1}, & \text{若 } T_{\text{prompt}} + T_{\text{out}} \le 256\text{K} \\
(0.1100,\; 0.000549,\; 1.7672)\,\text{M}^{-1}, & \text{若 } T_{\text{prompt}} + T_{\text{out}} > 256\text{K}
\end{cases}
K3 与 K3-256k 的唯一区别是:仅当 T_{\text{prompt}} > 256\text{K} 时 K3-256k 返回 400 报错;若 T_{\text{prompt}} < 256\text{K} 而加上输出后实际总长超过 256\text{K} ,K3-256k 同样正常返回并按 2\times 计费。
3.2 全模型计费权重总表与对比
汇总当前订阅内全部 6 个模型的拟合权重、满额容量及国内站 API 定价见表 2 与图 2。
表 2 权重单位均为 \text{M}^{-1} ,7d 权重为 5h 的 \frac{1}{5} 。K3.1 系列在两次测试间调整过权重,表中分别列出 10 月 24 日与 10 月 25 日两次测试的结果,其余模型两轮一致。
表 2:老版 Allegro 套餐全模型计费权重、满额容量与国内站 API 定价总表
| 模型名称 | 分段条件 | w_{\text{in},5\text{h}} | w_{\text{cr},5\text{h}} | w_{\text{out},5\text{h}} | w_{\text{in},7\text{d}} | w_{\text{cr},7\text{d}} | w_{\text{out},7\text{d}} | 5h 满额纯输入 / 纯输出 | 内部比例 w_{\text{in}} : w_{\text{cr}} : w_{\text{out}} | 国内站 API 入/缓/出 ( \text{元/M} ) | 相对 K3(总长 \le 256\text{K} )倍率 |
|---|---|---|---|---|---|---|---|---|---|---|---|
K2.7 Code Highspeed | — | 0.2000 | 0.001000 | 2.0000 | 0.04000 | 0.000200 | 0.40000 | 5.00\text{M} / 0.500\text{M} | 1 : \frac{1}{200} : 10.00 | 13.70 / 2.74 / 57.60 | 1.818 / 1.821 / 2.263\times (K2.8 的 3\times ) |
K2.8 Preview | — | \frac{1}{15} ( 0.06667 ) | \frac{1}{3000} ( 0.000333 ) | \frac{2}{3} ( 0.66667 ) | \frac{1}{75} | \frac{1}{15000} | \frac{2}{15} | 15.00\text{M} / 1.500\text{M} | 1 : \frac{1}{200} : 10.00 | 6.80 / 1.36 / 28.80 | 0.606 / 0.607 / 0.754\times |
K3 / K3-256k | T_{\text{prompt}} + T_{\text{out}} \le 256\text{K} | 0.1100 | 0.000549 | 0.8836 | 0.02200 | 0.000110 | 0.17672 | 9.09\text{M} / 1.132\text{M} | 1 : \frac{1}{200} : 8.03 | 20.00 / 2.00 / 100.00 | 1.000\times (基准) |
K3 / K3-256k | T_{\text{prompt}} + T_{\text{out}} > 256\text{K} | 0.1100 | 0.000549 | 1.7672 | 0.02200 | 0.000110 | 0.35344 | 9.09\text{M} / 0.566\text{M} | 1 : \frac{1}{200} : 16.07 | 20.00 / 2.00 / 100.00 | 入/缓 1\times ,出 2\times |
K3.1 Pro(10 月 24 日测试) | — | 0.14400 | 0.000750 | 1.15600 | 0.02880 | 0.000150 | 0.23120 | 6.94\text{M} / 0.865\text{M} | 1 : \frac{1}{192} : 8.03 | 13.00 / 1.30 / 68.00 | 1.309 / 1.366 / 1.308\times |
K3.1 Pro(10 月 25 日测试) | — | 0.0936 | 0.000473 | 0.751 | 0.01872 | 0.0000946 | 0.1502 | 10.68\text{M} / 1.332\text{M} | 1 : \frac{1}{198} : 8.02 | 13.00 / 1.30 / 68.00 | 0.851 / 0.862 / 0.850\times |
K3.1 Pro Highspeed(10 月 24 日测试) | — | 0.28800 | 0.001500 | 2.31200 | 0.05760 | 0.000300 | 0.46240 | 3.47\text{M} / 0.433\text{M} | 1 : \frac{1}{192} : 8.03 | 26.00 / 1.30 / 136.00 | 2.62\times (K3.1 Pro 的 2\times ) |
K3.1 Pro Highspeed(10 月 25 日测试) | — | 0.1872 | 0.000946 | 1.502 | 0.03744 | 0.000189 | 0.3004 | 5.34\text{M} / 0.666\text{M} | 1 : \frac{1}{198} : 8.02 | 26.00 / 1.30 / 136.00 | 1.70\times (K3.1 Pro 的 2\times ) |
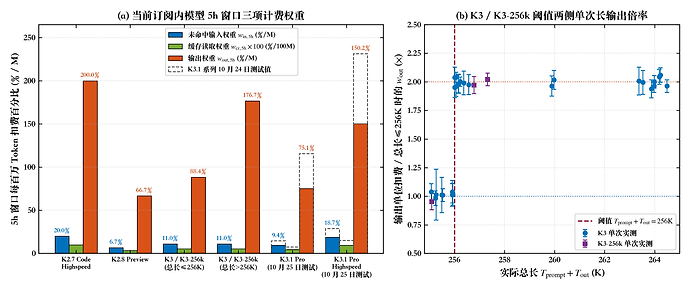
表 2 中值得注意的几处细节:
K3与K3.1 Pro的套餐/API 价格关系:国内站按量 API 上,K3.1 Pro( 13 / 1.3 / 68\text{ 元/M} )约为K3( 20 / 2 / 100\text{ 元/M} )的 0.65 \sim 0.68\times 。10 月 24 日首轮实测时,套餐内K3.1 Pro的扣费权重是K3的 1.31\times ,存在倒挂;10 月 25 日凌晨复测时下调为K3的约 0.85\times ,但相对比例仍高于两者在按量 API 上的价格比。- 缓存读取统一约为未命中输入的 1/200:
K2.8 Preview的 w_{\text{cr}} 可行区间为 [0.000328, 0.000342]\,\text{M}^{-1} ,与 \frac{1}{3000} 吻合;K3为 w_{\text{in}} / 200.4 ,K3.1 Pro为 w_{\text{in}} / 198 。两代模型的差别在输出倍率:K2 系列为 10\times ,K3 / K3.1 系列约为 8.0\times 。 - 高速版为标准版的固定倍数:
K3.1 Pro Highspeed为K3.1 Pro的 2\times ,K2.7 Code Highspeed为K2.8 Preview的 3\times ,三项同步放大。国内站 API 上高速版的缓存读取不加价,套餐内则与输入、输出同步放大。
4. 套餐额度折算国内站 API 的人民币价值
由于套餐内部的三项权重比例与国内站按量 API 的单价比例不同,满额度能折合多少按量 API 费用,取决于日常使用时的上下文缓存命中率 h = \frac{T_{\text{cr}}}{T_{\text{in}} + T_{\text{cr}}} 与未命中输入/输出比 r = \frac{T_{\text{in}}}{T_{\text{out}}} 。
设某模型在国内站 API 的单价为 (P_{\text{in}}, P_{\text{cr}}, P_{\text{out}}) (单位: \text{元/M} ),其在 5h 窗口的权重为 (w_{\text{in},5\text{h}}, w_{\text{cr},5\text{h}}, w_{\text{out},5\text{h}}) ,则单次 5h 满额度下的最大输出量 S_{\text{out},5\text{h}}^{\max} 及 5h、7d 满额度折算的国内站 API 人民币金额 V_{5\text{h}}, V_{7\text{d}} 为:
S_{\text{out},5\text{h}}^{\max}(r, h) = \frac{1}{w_{\text{in},5\text{h}} \cdot r + w_{\text{cr},5\text{h}} \cdot r \frac{h}{1-h} + w_{\text{out},5\text{h}}}
V_{5\text{h}}(r, h) = \frac{P_{\text{in}} \cdot r + P_{\text{cr}} \cdot r \frac{h}{1-h} + P_{\text{out}}}{w_{\text{in},5\text{h}} \cdot r + w_{\text{cr},5\text{h}} \cdot r \frac{h}{1-h} + w_{\text{out},5\text{h}}}, \qquad V_{7\text{d}}(r, h) = 5\,V_{5\text{h}}(r, h)
以下统一按参考工况估算:长文编码场景,缓存命中率 h = 97.5\% 、未命中输入 : 输出 r = 2.5 。代入表 2 的权重,各模型折算结果见表 3 与图 3。K3.1 系列在两次测试间调整过权重,表中分别列出两次测试的结果,其余模型两次测试一致。
表 3:参考工况( h = 97.5\% 、 r = 2.5 )下各模型满额度的国内站 API 人民币等效价值
| 模型 | 5h 满额度可用输出 ( S_{\text{out},5\text{h}}^{\max} ) | 5h 满额度等效 ( V_{5\text{h}} ) | 7d 满额度等效 ( V_{7\text{d}} ) | 每 1\% 5h 配额折合 |
|---|---|---|---|---|
K2.7 Code Highspeed | 385.0\text{K} | 138.2\text{ 元} | 691.0\text{ 元} | 1.38\text{ 元} |
K2.8 Preview | 1{,}155.0\text{K} | 206.0\text{ 元} | 1{,}030.2\text{ 元} | 2.06\text{ 元} |
K3 / K3-256k(总长 \le 256\text{K} ) | 825.0\text{K} | 284.6\text{ 元} | 1{,}423.1\text{ 元} | 2.85\text{ 元} |
K3 / K3-256k(总长 > 256\text{K} ) | 477.2\text{K} | 164.6\text{ 元} | 823.1\text{ 元} | 1.65\text{ 元} |
K3.1 Pro(10 月 24 日测试) | 629.3\text{K} | 143.0\text{ 元} | 715.0\text{ 元} | 1.43\text{ 元} |
K3.1 Pro(10 月 25 日测试) | 969.8\text{K} | 220.4\text{ 元} | 1{,}102.0\text{ 元} | 2.20\text{ 元} |
K3.1 Pro Highspeed(10 月 24 日测试) | 314.6\text{K} | 103.1\text{ 元} | 515.6\text{ 元} | 1.03\text{ 元} |
K3.1 Pro Highspeed(10 月 25 日测试) | 484.9\text{K} | 158.9\text{ 元} | 794.6\text{ 元} | 1.59\text{ 元} |
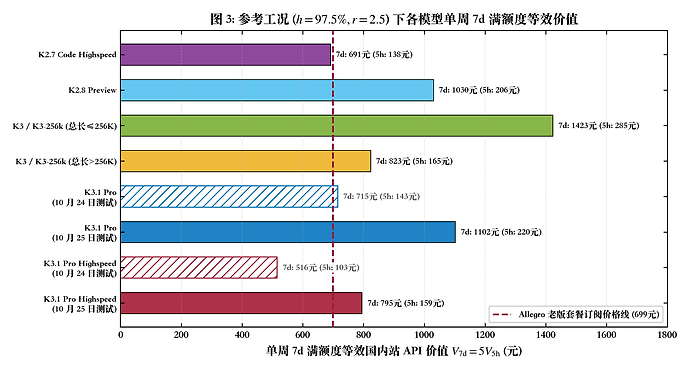
在参考工况下,K3.1 Pro 按复测权重单周 7d 满额度即折合官方 API 1{,}102.0\text{ 元} (首轮权重下为 715.0\text{ 元} ),单周额度已超过 699 元月费。K3(总长 \le 256\text{K} )的等效价值最高,达 1{,}423.1\text{ 元} ,原因是 K3 的国内站 API 单价是 K3.1 Pro 的 1.47 \sim 1.54\times ,而套餐扣费权重只高 1.17\times 。
5. 流式输出吞吐与首 Token 延迟(TPS / TTFT)实测
在测试计费权重的同时,也在 SSE 流式请求中记录了请求发出、首包到达、末包到达与流结束时刻,测出各模型在不同上下文长度下的首 Token 延迟 \text{TTFT} 、长输出持续解码速率 \text{TPS}_{\text{dec}} (扣除 \text{TTFT} ,取 1.5\text{K} \sim 2\text{K} 长输出样本)及端到端速率 \text{TPS}_{\text{E2E}} ,实测均值及范围见表 4。
注:表 4 数据测于 10 月 24 日早上 6:10–6:32,仅代表该时段 Kimi 计算集群的负载状态,TPS 仅作参考,具体仍受限于实际输出内容分布。每个模型的长输出样本仅 n = 2 ,部分模型两次差异较大(如
K2.8 Preview为 51.0 / 135.3\,\text{tok/s} ),排序仅供参考;K3-256k第 2 次长输出提前结束(仅 412 Token),但仍计入了均值。
表 4:10 月 24 日早上实测订阅内模型客户端流式输出吞吐率 ( \text{TPS}_{\text{dec}}, \text{TPS}_{\text{E2E}} ) 与多档位首 Token 延迟 ( \text{TTFT} ) 实测表
| 模型名称 | 短输入 \text{TTFT} ( \sim 100\,\text{tok} ) | 51.2\text{K} 未缓存预填充 \text{TTFT} (按 T_{\text{prompt}} / \text{TTFT} 折算输入速率) | 51.2\text{K} 缓存命中 \text{TTFT} | 256\text{K} \sim 333\text{K} 缓存命中 \text{TTFT} | 长输出持续吞吐率 \text{TPS}_{\text{dec}} ( 1.5\text{K} \sim 2\text{K} ) | 长输出端到端速率 \text{TPS}_{\text{E2E}} |
|---|---|---|---|---|---|---|
K2.7 Code Highspeed | 0.91\,\text{s} ( 0.83\sim 0.98\,\text{s} ) | 10.42\,\text{s} ( \sim 4.9\text{K/s} ) | 1.63\,\text{s} ( 1.48\sim 1.73\,\text{s} ) | (上限 256K) | 230.0\,\text{tok/s} ( 186.8\sim 273.3 ) | 208.6\,\text{tok/s} |
K2.8 Preview | 0.62\,\text{s} ( 0.60\sim 0.63\,\text{s} ) | 6.50\,\text{s} ( \sim 7.9\text{K/s} ) | 2.51\,\text{s} (中位 1.20\,\text{s} ) | — | 93.2\,\text{tok/s} ( 51.0\sim 135.3 ) | 90.1\,\text{tok/s} |
K3 ( \le 256\text{K} ) | 1.41\,\text{s} ( 0.98\sim 1.84\,\text{s} ) | 7.71\,\text{s} ( \sim 6.6\text{K/s} ) | 4.95\,\text{s} ( 1.50\sim 10.44\,\text{s} ) | 16.33\,\text{s} ( @256\text{K} ) | 61.9\,\text{tok/s} ( 59.7\sim 64.0 ) | 59.4\,\text{tok/s} |
K3-256k | 1.86\,\text{s} ( 1.00\sim 2.72\,\text{s} ) | 6.30\,\text{s} ( \sim 8.1\text{K/s} ) | 5.44\,\text{s} ( 3.52\sim 9.37\,\text{s} ) | 18.64\,\text{s} ( @256\text{K} ) | 51.7\,\text{tok/s} ( 51.5\sim 51.9 ) | 44.5\,\text{tok/s} |
K3 ( > 256\text{K} @333\text{K} ) | — | 21.73\,\text{s} ( 271\text{K} 未缓存, 12.5\text{K/s} ) | — | 20.85\,\text{s} ( @333\text{K} ) | 44.3\,\text{tok/s} ( 37.2\sim 51.3 ) | 29.8\,\text{tok/s} |
K3.1 Pro | 1.22\,\text{s} ( 0.95\sim 1.49\,\text{s} ) | 3.14\,\text{s} ( \sim 16.3\text{K/s} ) | 2.22\,\text{s} ( 1.54\sim 2.89\,\text{s} ) | — | 68.7\,\text{tok/s} ( 67.5\sim 69.9 ) | 65.0\,\text{tok/s} |
K3.1 Pro Highspeed | 0.80\,\text{s} ( 0.77\sim 0.83\,\text{s} ) | 3.17\,\text{s} ( \sim 16.2\text{K/s} ) | 1.39\,\text{s} ( 1.18\sim 1.72\,\text{s} ) | — | 124.6\,\text{tok/s} ( 120.7\sim 128.5 ) | 116.7\,\text{tok/s} |
表 4 中最值得关注的是预填充与缓存命中 \text{TTFT} 的反转现象:在 51.2\text{K} 未缓存预填充时,K3.1 Pro 比 K2.8 Preview 快一倍以上( 3.14\,\text{s} vs 6.50\,\text{s} );但同样长度一旦命中缓存,K3 / K3.1 的首包响应(K3.1 Pro 2.22\,\text{s} 、K3 4.95\,\text{s} )反而比 K2(中位 1.20\,\text{s} )更慢。
附录
附带了Argon写的小脚本,供大家参考。
附录 A:快速测算脚本(kimi_plan_quick_probe.py)
功能说明:耗时约 40\,\text{s} ,发送 4 次校准请求(消耗约 1.0\% \sim 1.5\%
5h配额),测算当前账户相对于老版 Allegro(699 元)套餐的配额容量缩放倍率,并输出当前订阅内模型可用 Token 上限、参考工况国内站 API 等效人民币价值及实测 \text{TTFT} 、 \text{TPS}_{\text{dec}} 。基准权重采用 10 月 25 日凌晨复测值,默认以K2.8 Preview(两轮实测权重一致)作为测算基准。
点击展开:kimi_plan_quick_probe.py 完整源码
#!/usr/bin/env python3

# -*- coding: utf-8 -*-

"""

Kimi Coding Plan 轻量级档位额度与倍率快速测算脚本

用法:

  export KIMI_API_KEY="sk-kimi-..."

  python kimi_plan_quick_probe.py

"""


import argparse

import json

import os

import sys

import time

import requests


BASE_URL = "https://api.kimi.com/coding/v1"


# 老版 Allegro (699元) 套餐实测权重 (5h 窗口每 M 消耗比例,2026-10-25 凌晨 UTC+8 复测)

# K3.1 系列在 2026-10-24 早上 UTC+8 首轮为 (0.144, 0.00075, 1.156) / (0.288, 0.0015, 2.312),之后被下调

# K3 / K3-256k 按实际总长 prompt_tokens + completion_tokens 是否 > 256K 分段,越过后整段输出 ×2

ALLEGRO_BASE_5H = {

    "K3.1 Pro":                  {"w_in": 0.0936,     "w_cr": 0.000473,     "w_out": 0.751,     "cn_api": (13.0, 1.30, 68.0)},

    "K3.1 Pro Highspeed":        {"w_in": 0.1872,     "w_cr": 0.000946,     "w_out": 1.502,     "cn_api": (26.0, 1.30, 136.0)},

    "K3 / K3-256k (总长≤256K)":  {"w_in": 0.1100,     "w_cr": 0.000549,     "w_out": 0.8836,    "cn_api": (20.0, 2.00, 100.0)},

    "K3 / K3-256k (总长>256K)":  {"w_in": 0.1100,     "w_cr": 0.000549,     "w_out": 1.7672,    "cn_api": (20.0, 2.00, 100.0)},

    "K2.8 Preview":              {"w_in": 1.0 / 15.0, "w_cr": 1.0 / 3000.0, "w_out": 2.0 / 3.0, "cn_api": (6.8,  1.36, 28.8)},

    "K2.7 Code Highspeed":       {"w_in": 0.20000,    "w_cr": 0.001000,     "w_out": 2.00000,   "cn_api": (13.7, 2.74, 57.6)},

}


def get_usages(api_key: str):

    headers = {"Authorization": f"Bearer {api_key}"}

    r = requests.get(f"{BASE_URL}/usages", headers=headers, timeout=10)

    r.raise_for_status()

    data = r.json()

    u5 = data["usages"]["limit_5h"]["used_ratio"]

    u7 = data["usages"]["limit_7d"]["used_ratio"]

    r5 = data["usages"]["limit_5h"]["reset_time"]

    r7 = data["usages"]["limit_7d"]["reset_time"]

    return u5, u7, r5, r7


def stream_call(api_key: str, model: str, messages: list, max_tokens: int):

    headers = {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}

    payload = {

        "model": model,

        "messages": messages,

        "max_tokens": max_tokens,

        "stream": True,

        "stream_options": {"include_usage": True},

    }

    t0 = time.perf_counter()

    r = requests.post(f"{BASE_URL}/chat/completions", headers=headers, json=payload, stream=True, timeout=180)

    r.raise_for_status()


    t_first = None

    t_last = None

    usage = {}

    for line in r.iter_lines():

        if not line:

            continue

        s = line.decode("utf-8", errors="replace")

        if not s.startswith("data: "):

            continue

        d = s[6:].strip()

        if d == "[DONE]":

            break

        try:

            obj = json.loads(d)

        except Exception:

            continue

        if obj.get("usage"):

            usage = obj["usage"]

        choices = obj.get("choices") or []

        if choices:

            delta = choices[0].get("delta") or {}

            if delta.get("reasoning_content") or delta.get("content"):

                if t_first is None:

                    t_first = time.perf_counter()

                t_last = time.perf_counter()


    t_end = time.perf_counter()

    ttft = (t_first - t0) if t_first else (t_end - t0)

    gen_t = (t_last - t_first) if (t_first and t_last and t_last > t_first) else 0.0

    pt = usage.get("prompt_tokens", 0)

    ct = usage.get("cached_tokens", 0) or (usage.get("prompt_tokens_details") or {}).get("cached_tokens", 0)

    out = usage.get("completion_tokens", 0)

    tps = (out / gen_t) if (gen_t > 0.05 and out > 0) else 0.0

    return pt - ct, ct, out, ttft, tps


def main():

    parser = argparse.ArgumentParser(description="Kimi Coding Plan 轻量级额度与倍率快速测算脚本")

    parser.add_argument("--api-key", default=os.environ.get("KIMI_API_KEY", ""), help="Kimi Coding API Key (sk-kimi-...)")

    parser.add_argument("--model", default="kimi-for-coding", choices=["k3.1-pro", "kimi-for-coding"],

                        help="用于测算的基准模型(kimi-for-coding 的权重两轮实测一致,作为默认基准)")

    args = parser.parse_args()


    api_key = args.api_key.strip()

    if not api_key:

        print("错误: 请通过 --api-key sk-kimi-... 或环境变量 KIMI_API_KEY 提供 API Key")

        sys.exit(1)


    u5_init, u7_init, r5, r7 = get_usages(api_key)

    print("=" * 76)

    print("  Kimi Coding Plan 轻量级额度与计费倍率测算")

    print("=" * 76)

    print(f"当前 5h 已用比例: {u5_init*100:.2f}% (重置时间: {r5})")

    print(f"当前 7d 已用比例: {u7_init*100:.2f}% (重置时间: {r7})")

    print("-" * 76)


    model = args.model

    offset = 96 if model == "k3.1-pro" else 97

    uid = str(int(time.time() * 1000))[-8:]

    sys_40k = f"Session {uid}: " + " ".join(["apple"] * (160 * 256 - offset))


    # Step 1: 40.96K 未命中输入测试

    b5, b7, _, _ = get_usages(api_key)

    in1, cr1, out1, ttft_pre, _ = stream_call(

        api_key, model,

        [{"role": "system", "content": sys_40k}, {"role": "user", "content": "Reply with the single word OK. [0]"}],

        max_tokens=32,

    )

    time.sleep(1.8)

    m5_1, m7_1, _, _ = get_usages(api_key)

    d5_in = m5_1 - b5

    print(f"[测试 1/3: 未缓存输入] in_miss={in1:6d}, cache={cr1:6d}, out={out1:4d} | delta_5h={d5_in:+.4f} | Prefill TTFT={ttft_pre:.2f}s")


    # Step 2: 2 次 40.96K 连续缓存命中测试 (逐次累加实际 Token 计数)

    in2_sum = cr2_sum = out2_sum = 0

    ttft_hit = 0.0

    for i in range(1, 3):

        in_c, cr_c, out_c, ttft_hit, _ = stream_call(

            api_key, model,

            [{"role": "system", "content": sys_40k}, {"role": "user", "content": f"Reply with the single word OK. [{i}]"}],

            max_tokens=16,

        )

        in2_sum += in_c

        cr2_sum += cr_c

        out2_sum += out_c

        time.sleep(1.5)

    m5_2, m7_2, _, _ = get_usages(api_key)

    d5_cr = m5_2 - m5_1

    print(f"[测试 2/3: 连续缓存x2] in_miss={in2_sum:6d}, cache={cr2_sum:6d}, out={out2_sum:4d} | delta_5h={d5_cr:+.4f} | CacheHit TTFT={ttft_hit:.2f}s")


    # Step 3: 2048 Token 输出测试

    uid_out = str(int(time.time() * 1000))[-8:]

    in3, cr3, out3, ttft_short, tps_dec = stream_call(

        api_key, model,

        [

            {"role": "system", "content": f"Session {uid_out}: Output benchmark."},

            {"role": "user", "content": "Write a continuous numbered list of short technical definitions in English from 1 to 2500, one per line."},

        ],

        max_tokens=2048,

    )

    time.sleep(1.8)

    u5_end, u7_end, _, _ = get_usages(api_key)

    d5_out = u5_end - m5_2

    print(f"[测试 3/3: 输出测试  ] in_miss={in3:6d}, cache={cr3:6d}, out={out3:4d} | delta_5h={d5_out:+.4f} | Short TTFT={ttft_short:.2f}s, Decode TPS={tps_dec:.1f} tok/s")


    tot_in = in1 + in2_sum + in3

    tot_cr = cr1 + cr2_sum + cr3

    tot_out = out1 + out2_sum + out3

    tot_d5 = u5_end - u5_init

    tot_d7 = u7_end - u7_init


    base = ALLEGRO_BASE_5H["K3.1 Pro" if model == "k3.1-pro" else "K2.8 Preview"]

    expected_allegro_5h = (base["w_in"] * tot_in + base["w_cr"] * tot_cr + base["w_out"] * tot_out) / 1e6


    capacity_scale = (expected_allegro_5h / tot_d5) if tot_d5 > 0 else 1.0

    if tot_d7 >= 0.0005:

        ratio_5h_to_7d = tot_d5 / tot_d7

        ratio_note = f"实测估计值 {ratio_5h_to_7d:.1f} : 1"

    else:

        ratio_5h_to_7d = 5.0

        ratio_note = "7d 增量较小,采用基准比例 5.0 : 1"


    print("\n" + "=" * 76)

    print("  测算结果汇总与当前订阅内模型额度推算")

    print("=" * 76)

    print(f"本次测试总消耗: 5h 额度 {tot_d5*100:.2f}% | 7d 额度 {tot_d7*100:.2f}%")

    print(f"Allegro (699元) 基准理论消耗 (2026-10-25 权重): 5h 额度 {expected_allegro_5h*100:.3f}%")

    print(f"--> 当前套餐 5h 额度容量约为老版 Allegro (699元) 套餐的: 【 {capacity_scale:.2f} 倍 】")

    print(f"--> 7d / 5h 窗口容量比: 【 {ratio_note} 】")

    print("-" * 76)

    print(f"{'模型名称':26s} | {'5h纯输入上限':12s} | {'5h纯输出上限':12s} | {'参考工况5h等效API':18s} | {'7d满额度等效API':14s}")

    print("-" * 76)


    r_in_out = 2.5

    h_cache = 0.975

    c_cr_out = r_in_out * h_cache / (1.0 - h_cache)


    for m_name, cfg in ALLEGRO_BASE_5H.items():

        w_in_user = cfg["w_in"] / capacity_scale

        w_cr_user = cfg["w_cr"] / capacity_scale

        w_out_user = cfg["w_out"] / capacity_scale


        max_in_m = 1.0 / w_in_user

        max_out_m = 1.0 / w_out_user


        p_in, p_cr, p_out = cfg["cn_api"]

        val_5h = (p_in * r_in_out + p_cr * c_cr_out + p_out) / (w_in_user * r_in_out + w_cr_user * c_cr_out + w_out_user)

        val_7d = val_5h * ratio_5h_to_7d


        print(f"{m_name:26s} | {max_in_m:9.2f} M | {max_out_m:9.2f} M | {val_5h:14.1f} 元/5h | {val_7d:11.1f} 元/7d")

    print("=" * 76)


if __name__ == "__main__":

    main()
附录 B:多模型权重拟合与线性规划求解脚本(kimi_plan_full_benchmark.py)
功能说明:自动化执行覆盖当前订阅内全部 6 个模型(含
K3在 256\text{K} 阈值两侧的测试,分析时按实际总长 T_{\text{prompt}} + T_{\text{out}} 是否超过 256\text{K} 分段,合计 62 次测试请求)的 256-Token 块对齐测试与流式 \text{TTFT} 、 \text{TPS}_{\text{dec}} 测量,并读取 JSONL 实验日志,自动按配额衔接拆分为连续实验段,同时对5h与7d窗口求解最大安全裕度中心解及三项权重的可行区间。
点击展开:kimi_plan_full_benchmark.py 完整源码
#!/usr/bin/env python3

# -*- coding: utf-8 -*-

"""

Kimi Coding Plan 多模型计费权重测定与流式吞吐基准测试脚本

用法:

  export KIMI_API_KEY="sk-kimi-..."

  python kimi_plan_full_benchmark.py --phase all

  python kimi_plan_full_benchmark.py --phase analyze --log bench_all_models_log.jsonl

"""


import argparse

import json

import os

import sys

import time

import requests

from scipy.optimize import linprog


BASE_URL = "https://api.kimi.com/coding/v1"

K3_THRESHOLD = 256000


OFFSETS = {

    "k3.1-pro": 96,

    "k3.1-pro-highspeed": 96,

    "k3-256k": 97,

    "k3": 97,

    "kimi-for-coding": 97,

    "kimi-for-coding-highspeed": 11,

}


def get_headers(api_key: str) -> dict:

    return {"Authorization": f"Bearer {api_key}", "Content-Type": "application/json"}


def get_usages(api_key: str):

    headers = get_headers(api_key)

    for attempt in range(5):

        try:

            r = requests.get(f"{BASE_URL}/usages", headers=headers, timeout=10)

            r.raise_for_status()

            data = r.json()

            return data["usages"]["limit_5h"]["used_ratio"], data["usages"]["limit_7d"]["used_ratio"], data

        except Exception:

            if attempt == 4:

                raise

            time.sleep(1.0)


def stream_chat(api_key: str, model: str, messages: list, max_tokens: int = 64):

    headers = get_headers(api_key)

    payload = {

        "model": model,

        "messages": messages,

        "max_tokens": max_tokens,

        "stream": True,

        "stream_options": {"include_usage": True},

    }

    t_start = time.perf_counter()

    r = requests.post(f"{BASE_URL}/chat/completions", headers=headers, json=payload, stream=True, timeout=300)

    if r.status_code != 200:

        return {

            "status_code": r.status_code,

            "error": r.text[:500],

            "ttft": None,

            "gen_time": None,

            "total_time": time.perf_counter() - t_start,

            "tps_decode": None,

            "tps_e2e": None,

            "usage": {},

        }


    t_first_token = None

    t_last_token = None

    chunk_count = 0

    usage = {}


    for line in r.iter_lines():

        if not line:

            continue

        s = line.decode("utf-8", errors="replace")

        if not s.startswith("data: "):

            continue

        data_str = s[6:].strip()

        if data_str == "[DONE]":

            break

        try:

            obj = json.loads(data_str)

        except Exception:

            continue

        if obj.get("usage"):

            usage = obj["usage"]

        choices = obj.get("choices") or []

        if choices:

            delta = choices[0].get("delta") or {}

            if delta.get("reasoning_content") or delta.get("content"):

                if t_first_token is None:

                    t_first_token = time.perf_counter()

                t_last_token = time.perf_counter()

                chunk_count += 1


    t_end = time.perf_counter()

    ttft = (t_first_token - t_start) if t_first_token else (t_end - t_start)

    gen_time = (t_last_token - t_first_token) if (t_first_token and t_last_token and t_last_token > t_first_token) else 0.0

    total_time = t_end - t_start

    comp_tokens = usage.get("completion_tokens", 0)

    tps_decode = (comp_tokens / gen_time) if (gen_time > 0.05 and comp_tokens > 0) else None

    tps_e2e = (comp_tokens / total_time) if (total_time > 0 and comp_tokens > 0) else None


    return {

        "status_code": 200,

        "ttft": round(ttft, 4),

        "gen_time": round(gen_time, 4),

        "total_time": round(total_time, 4),

        "chunks": chunk_count,

        "tps_decode": round(tps_decode, 2) if tps_decode else None,

        "tps_e2e": round(tps_e2e, 2) if tps_e2e else None,

        "usage": usage,

    }


def make_aligned_sys(model: str, blocks_256: int, uid: str = None):

    if uid is None:

        uid = str(int(time.time() * 1000))[-8:]

    offset = OFFSETS.get(model, 97)

    n_apples = blocks_256 * 256 - offset

    return f"Session {uid}: " + " ".join(["apple"] * n_apples), uid


def short_output_msgs(uid: str, target_words: int = 3000):

    return [

        {"role": "system", "content": f"Session {uid}: Output generator."},

        {

            "role": "user",

            "content": (

                f"Write a continuous numbered list of short technical definitions in English from 1 to {target_words}, "

                "one per line, without stopping early."

            ),

        },

    ]


def run_step(api_key: str, log_path: str, tag: str, model: str, messages: list, max_tokens: int = 64, sleep_after: float = 1.8):

    b5, b7, _ = get_usages(api_key)

    res = stream_chat(api_key, model, messages, max_tokens=max_tokens)

    time.sleep(sleep_after)

    a5, a7, _ = get_usages(api_key)


    u = res.get("usage") or {}

    pt = u.get("prompt_tokens", 0)

    ct = u.get("cached_tokens", 0) or (u.get("prompt_tokens_details") or {}).get("cached_tokens", 0)

    in_miss = pt - ct

    out_tok = u.get("completion_tokens", 0)

    reas_tok = (u.get("completion_tokens_details") or {}).get("reasoning_tokens", 0)


    d5, d7 = round(a5 - b5, 4), round(a7 - b7, 4)

    record = {

        "ts": time.time(),

        "tag": tag,

        "model": model,

        "status_code": res["status_code"],

        "error": res.get("error"),

        "prompt_tokens": pt,

        "cached_tokens": ct,

        "in_miss": in_miss,

        "completion_tokens": out_tok,

        "reasoning_tokens": reas_tok,

        "ttft": res.get("ttft"),

        "gen_time": res.get("gen_time"),

        "total_time": res.get("total_time"),

        "tps_decode": res.get("tps_decode"),

        "tps_e2e": res.get("tps_e2e"),

        "before_5h": b5,

        "after_5h": a5,

        "delta_5h": d5,

        "before_7d": b7,

        "after_7d": a7,

        "delta_7d": d7,

    }

    with open(log_path, "a", encoding="utf-8") as f:

        f.write(json.dumps(record, ensure_ascii=False) + "\n")


    print(

        f"[{tag:30s}] model={model:25s} | in_miss={in_miss:7d} cache={ct:7d} out={out_tok:5d} (reas={reas_tok:4d}) "

        f"| 5h: {b5:.4f}->{a5:.4f} ({d5:+.4f}) | 7d: {b7:.4f}->{a7:.4f} ({d7:+.4f}) "

        f"| TTFT={str(res.get('ttft')):6s}s TPS={str(res.get('tps_decode')):6s}",

        flush=True,

    )

    return record


def solve_lp_segment(name: str, seg_rows: list, window: str = "5h"):

    """

    基于连续实验段的线性规划区间拟合求解器:

    自动按相邻检查点配额读数衔接关系拆分为连续无间断子段(避免跨模型交替调用时直接累加造成混杂),

    并在每个连续子段内引入该子段的初始未四舍五入潜变量,联立求解最大安全裕度中心解与各权重的可行区间。

    """

    valid = [r for r in seg_rows if r.get("status_code", 200) == 200]

    if not valid:

        return


    b_key = f"before_{window}"

    a_key = f"after_{window}"

    delta = 0.00005


    # 将记录按配额衔接拆分为连续子段 (sub-segments)

    sub_segments = []

    cur_seg = [valid[0]]

    for r in valid[1:]:

        if abs(r[b_key] - cur_seg[-1][a_key]) < 1e-6:

            cur_seg.append(r)

        else:

            sub_segments.append(cur_seg)

            cur_seg = [r]

    sub_segments.append(cur_seg)


    num_segs = len(sub_segments)

    # 决策变量顺序: [x0_0, ..., x0_{S-1}, w_in, w_cr, w_out, eps]

    dim_total = num_segs + 4

    idx_win = num_segs

    idx_wcr = num_segs + 1

    idx_wout = num_segs + 2

    idx_eps = num_segs + 3


    A_ub = []

    b_ub = []

    A_ub_proj = []

    b_ub_proj = []


    tot_in = tot_cr = tot_out = 0.0

    bounds_main = []


    for s_idx, seg in enumerate(sub_segments):

        b0 = seg[0][b_key]

        bounds_main.append((b0 - delta, b0 + delta))


        # k = 0 初始检查点约束: |x0_s - b0| + eps <= delta

        row_pos = [0.0] * dim_total

        row_neg = [0.0] * dim_total

        row_pos[s_idx], row_pos[idx_eps] = 1.0, 1.0

        row_neg[s_idx], row_neg[idx_eps] = -1.0, 1.0

        A_ub.extend([row_pos, row_neg])

        b_ub.extend([b0 + delta, -b0 + delta])


        A_ub_proj.extend([row_pos[:num_segs + 3], row_neg[:num_segs + 3]])

        b_ub_proj.extend([b0 + delta, -b0 + delta])


        cum_in = cum_cr = cum_out = 0.0

        for r in seg:

            cum_in += r["in_miss"] / 1e6

            cum_cr += r["cached_tokens"] / 1e6

            cum_out += r["completion_tokens"] / 1e6

            y = r[a_key]


            rp = [0.0] * dim_total

            rn = [0.0] * dim_total

            rp[s_idx], rp[idx_win], rp[idx_wcr], rp[idx_wout], rp[idx_eps] = 1.0, cum_in, cum_cr, cum_out, 1.0

            rn[s_idx], rn[idx_win], rn[idx_wcr], rn[idx_wout], rn[idx_eps] = -1.0, -cum_in, -cum_cr, -cum_out, 1.0

            A_ub.extend([rp, rn])

            b_ub.extend([y + delta, -y + delta])


            A_ub_proj.extend([rp[:num_segs + 3], rn[:num_segs + 3]])

            b_ub_proj.extend([y + delta, -y + delta])


        tot_in += cum_in

        tot_cr += cum_cr

        tot_out += cum_out


    bounds_proj = list(bounds_main) + [(0.0, None), (0.0, None), (0.0, None)]

    bounds_main.extend([(0.0, None), (0.0, None), (0.0, None), (0.0, delta)])


    c_obj = [0.0] * dim_total

    c_obj[idx_eps] = -1.0

    res_margin = linprog(c_obj, A_ub=A_ub, b_ub=b_ub, bounds=bounds_main, method="highs")


    print(

        f"\n=== [{name} | window={window}] ({len(valid)} steps across {num_segs} contiguous segments | "

        f"in={tot_in*1e6:.0f}, cr={tot_cr*1e6:.0f}, out={tot_out*1e6:.0f}) ==="

    )

    if res_margin.success:

        win = res_margin.x[idx_win]

        wcr = res_margin.x[idx_wcr]

        wout = res_margin.x[idx_wout]

        eps = res_margin.x[idx_eps]

        print(f"  Max-Safety-Margin Solution ({window} / M): w_in={win:.6f}, w_cr={wcr:.6f}, w_out={wout:.6f} (margin eps*={eps:.6f})")

        for idx_w, wname in [(idx_win, "w_in"), (idx_wcr, "w_cr"), (idx_wout, "w_out")]:

            c_min = [0.0] * (num_segs + 3)

            c_max = [0.0] * (num_segs + 3)

            c_min[idx_w], c_max[idx_w] = 1.0, -1.0

            rmin = linprog(c_min, A_ub=A_ub_proj, b_ub=b_ub_proj, bounds=bounds_proj, method="highs")

            rmax = linprog(c_max, A_ub=A_ub_proj, b_ub=b_ub_proj, bounds=bounds_proj, method="highs")

            if rmin.success and rmax.success:

                print(f"  {wname:6s} feasible interval: [{rmin.x[idx_w]:.6f}, {rmax.x[idx_w]:.6f}]")

    else:

        print("  Warning: No strictly feasible solution with eps >= 0 under current rounding bound.")


def run_all_benchmarks(api_key: str, log_path: str):

    for m, prefix in [

        ("k3.1-pro", "k31pro"),

        ("k3.1-pro-highspeed", "k31hs"),

        ("kimi-for-coding", "kfc"),

        ("kimi-for-coding-highspeed", "kfchs"),

        ("k3-256k", "k3_256k"),

        ("k3", "k3_lt256k"),

    ]:

        sys_51k, _ = make_aligned_sys(m, 200)

        run_step(api_key, log_path, f"{prefix}_warm_51k", m,

                 [{"role": "system", "content": sys_51k}, {"role": "user", "content": "Reply with the single word OK. [0]"}], max_tokens=32)

        for i in range(1, 7):

            run_step(api_key, log_path, f"{prefix}_hit_51k_{i}", m,

                     [{"role": "system", "content": sys_51k}, {"role": "user", "content": f"Reply with the single word OK. [{i}]"}], max_tokens=16)

        for i in range(1, 3):

            uid = str(int(time.time() * 1000))[-8:]

            run_step(api_key, log_path, f"{prefix}_out_{i}", m, short_output_msgs(uid), max_tokens=1500 if "hs" in prefix else 2048)


    # k3 >256K 区间测试

    sys_271k, _ = make_aligned_sys("k3", 1060)

    run_step(api_key, log_path, "k3_gt256k_warm_271k", "k3",

             [{"role": "system", "content": sys_271k}, {"role": "user", "content": "Reply with the single word OK. [0]"}], max_tokens=16)

    for i in range(1, 6):

        run_step(api_key, log_path, f"k3_gt256k_hit_271k_{i}", "k3",

                 [{"role": "system", "content": sys_271k}, {"role": "user", "content": f"Reply with the single word OK. [{i}]"}], max_tokens=16)

    for i in range(1, 3):

        run_step(api_key, log_path, f"k3_gt256k_out_2048_{i}", "k3",

                 [{"role": "system", "content": sys_271k},

                  {"role": "user", "content": f"Ignore the apples above. Write a numbered list of short definitions from 1 to 3000. [{i}]"}],

                 max_tokens=2048)


if __name__ == "__main__":

    parser = argparse.ArgumentParser(description="Kimi Coding Plan 多模型计费权重测定与吞吐测试")

    parser.add_argument("--api-key", default=os.environ.get("KIMI_API_KEY", ""), help="Kimi Coding API Key (sk-kimi-...)")

    parser.add_argument("--phase", default="analyze", choices=["all", "analyze"], help="执行测试序列 (all) 或分析已有日志 (analyze)")

    parser.add_argument("--log", default="bench_all_models_log.jsonl", help="JSONL (JSON Lines) 日志路径")

    parser.add_argument("--window", default="both", choices=["5h", "7d", "both"], help="拟合窗口选择")

    args = parser.parse_args()


    if args.phase == "all":

        if not args.api_key:

            print("请通过 --api-key 或环境变量 KIMI_API_KEY 提供 API Key", file=sys.stderr)

            sys.exit(1)

        run_all_benchmarks(args.api_key, args.log)


    if os.path.exists(args.log):

        rows = [json.loads(line) for line in open(args.log, encoding="utf-8")]

        windows = ["5h", "7d"] if args.window == "both" else [args.window]

        for w in windows:

            for m in ["k3.1-pro", "k3.1-pro-highspeed", "kimi-for-coding", "kimi-for-coding-highspeed"]:

                solve_lp_segment(m, [r for r in rows if r["model"] == m], window=w)

            # k3 / k3-256k 按实际总长 prompt + completion 是否 > 256K 分段(越过后整段输出 ×2)

            k3_rows = [r for r in rows if r["model"] in ("k3", "k3-256k")]

            solve_lp_segment("k3 / k3-256k (总长<=256K)", [r for r in k3_rows if r["prompt_tokens"] + r["completion_tokens"] <= K3_THRESHOLD], window=w)

            solve_lp_segment("k3 / k3-256k (总长>256K)", [r for r in k3_rows if r["prompt_tokens"] + r["completion_tokens"] > K3_THRESHOLD], window=w)
- ↑GrokBot全是路由到Grok4.5 ? !
- ↑iOS端 论坛专属新徽章
- ↑ChatGPT 网页版 5.6 Sol 智力恢复? 有没有一样的
- ↑把国外模型销售给中国企业,还是把中国模型销售给海外企业,哪个需求更大?更长期有市场?
- 📍 【我在L站搞科研】浅析 Kimi 会员计划模型计费制度:以 Allegro 套餐 Code 额度为例
- ↓如何升级3级
- ↓无限额度的Fable, Gemini Argon, Codex Astra和几乎无限的H200做什么比较有价值呢?
- ↓求好用的机场推荐
- ↓有没有做ai剧的佬友交流一下
- ↓苹果订阅claude pro明明商店有余额为什么一直支付不成功?